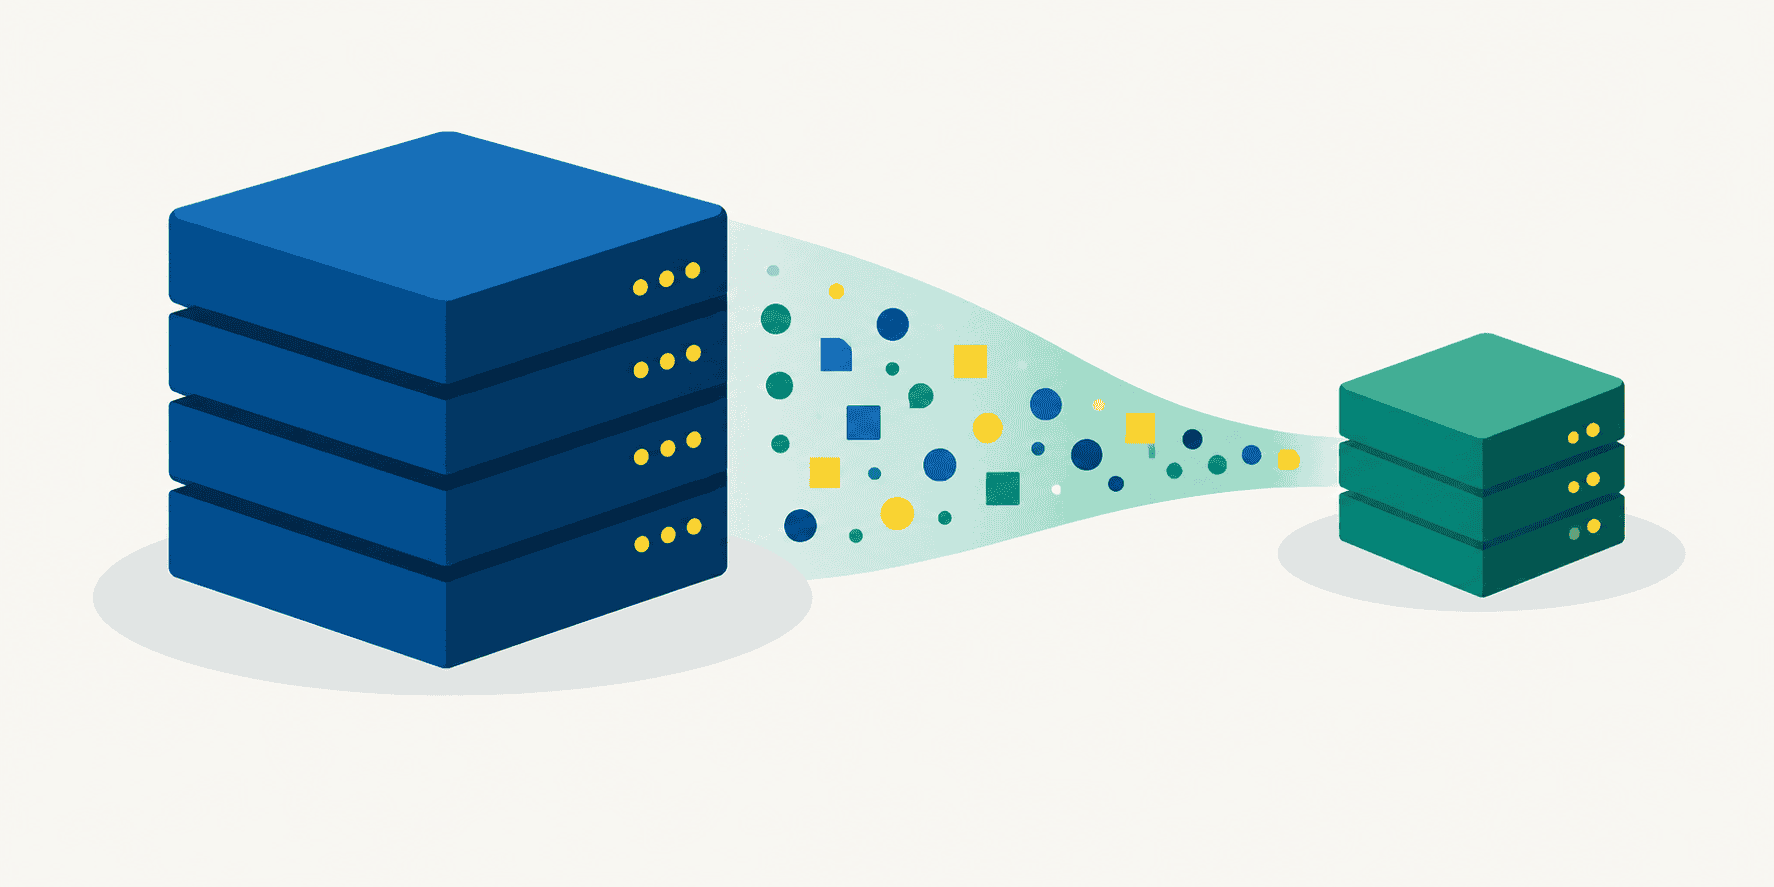
The most capable AI models are also the most impractical. GPT-4 and Gemini require massive data centers, making them too slow and expensive for everyday devices. Model distillation offers a solution by shrinking these giants into efficient “student” models. But this technical fix has sparked a fierce industry debate over intellectual property and unauthorized use.
Geoffrey Hinton introduced the core concept in 2015. He argued that standard training labels waste information. A photo of a dog isn’t just a “dog.” It shares visual traits with cats and wolves. A trained teacher model captures these nuances in its probability outputs. Hinton called this hidden structure “dark knowledge.” By forcing a student model to mimic these soft probabilities rather than just hard labels, developers transfer deep reasoning capabilities without the computational bulk.
Temperature scaling makes this possible. Teacher models often output near-100% confidence for the correct answer, which hides useful relational data. Raising the temperature flattens these distributions. This exposes subtle similarities between classes. The student learns not only the right answer but also which wrong answers are plausible. Hinton, Vinyals, and Dean proved this approach could match large ensembles with a fraction of the parameters. It turned brute force into elegant efficiency.
Modern large language models complicate this picture. They generate text token by token from vocabularies exceeding 100,000 options. Classical categorical distillation doesn’t translate directly to sequential generation. Developers now rely on synthetic data and logit-based approaches to bridge the gap. Yet the real tension isn’t technical. It is legal. Companies are distilling proprietary models at scale without permission. This practice threatens the business models of AI leaders who spent hundreds of millions on training. As distillation becomes easier, the line between innovation and theft blurs. The industry must decide if efficiency justifies bypassing the creators.