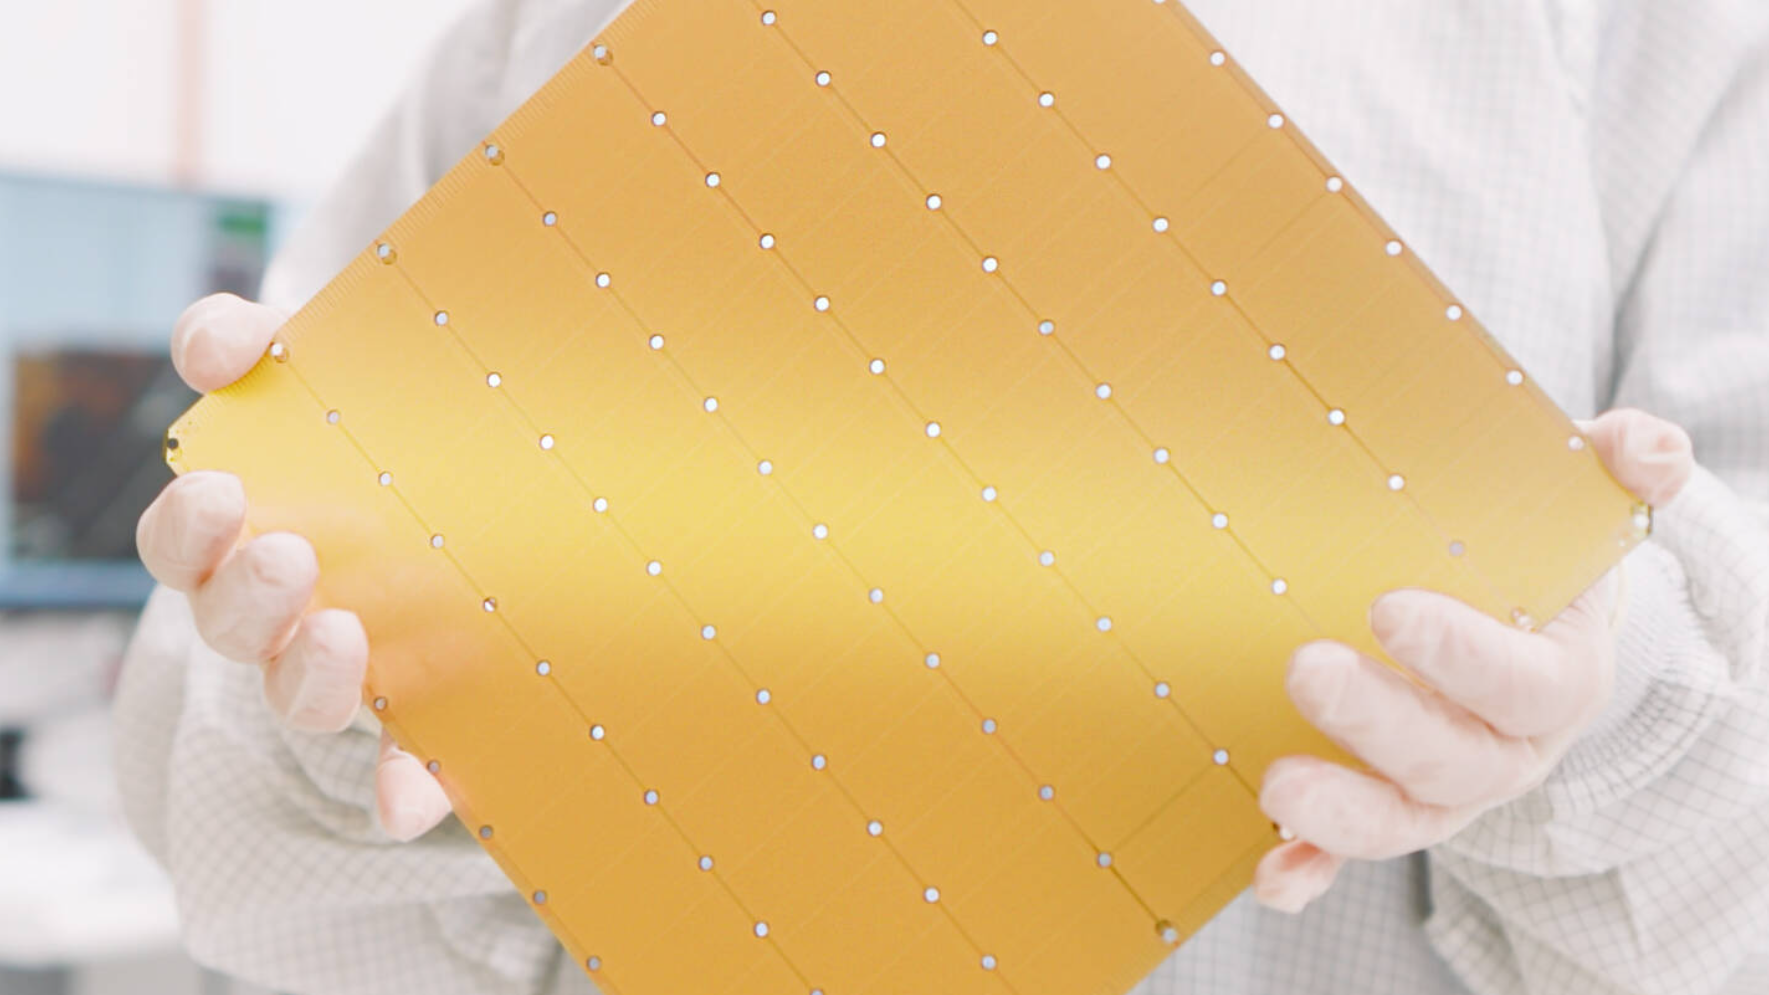
Cerebras is back with the CS-4, and the pitch is the same as ever: raw inference speed that makes GPU clusters look like they’re standing still. CEO Andrew Feldman claims the new rack-scale system is the fastest in the industry, and the headline number backs him up — 4,400 tokens per second per user, which Cerebras says is up to 30 times faster than comparable Nvidia GPU setups.
What’s interesting is what hasn’t changed. The CS-4 still runs on the 5nm WSE-3 wafer-scale chip, same 44 GB of memory per wafer. No architectural overhaul, no node shrink. Instead, Cerebras squeezed out double the performance by cranking clock speeds with more aggressive power delivery and cooling. A single rack now packs three wafers instead of two. It’s a classic overclocking move, just at data-center scale.
The company is also pushing a modular “Backpack” design for faster assembly and leaning into disaggregated inference through partners like AMD and AWS Trainium. That’s the strategic shift worth watching — Cerebras positioning itself as a fast-inference layer that plays nice with other vendors’ infrastructure rather than a walled garden. OpenAI already uses Cerebras hardware for Codex Spark, so there’s real production traction.
But analysts at SemiAnalysis are throwing cold water on the networking gains, calling them fairly small. And memory stays flat at 44 GB per wafer, which could be a bottleneck for large-context workloads where GPUs with massive HBM pools still hold an edge. The full technical picture lands at Hot Chips. Until then, the CS-4 looks like a meaningful speed bump — but maybe not the category redefinition Cerebras wants you to believe.


